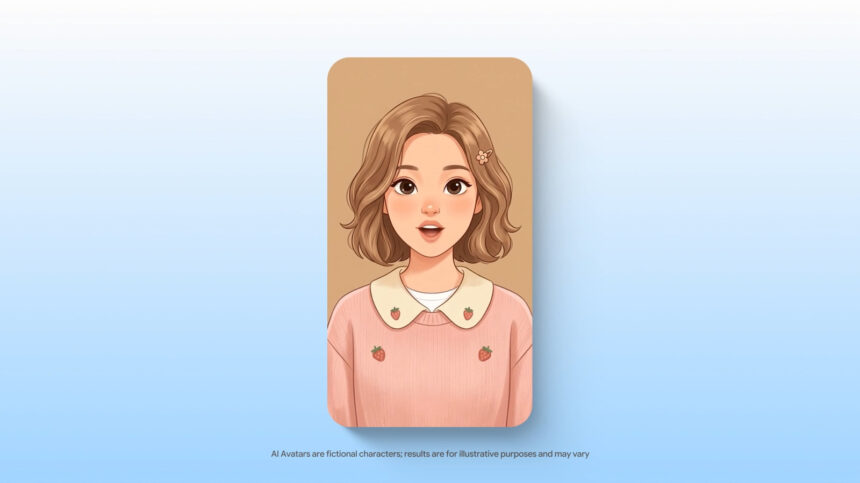
Google is expanding its enterprise artificial intelligence portfolio by bringing dynamic visual presences to real-time voice interactions. The introduction of Gemini 3.8 Live with Live Avatar combines high-throughput conversational models with generative visual pipelines, allowing business applications to present synthetic human or stylized digital agents directly to customers. Built upon the foundation of Google’s Gemini 3.8 Live dialogue infrastructure, this feature aims to transform standard voice interactions into fully multimodal visual exchanges. Rather than relying solely on audio output or static text interfaces, enterprise organizations can now deploy responsive synthetic personas capable of looking, listening, and speaking simultaneously. This shift represents a broader push within the enterprise technology sector to humanize automated customer support and interactive sales flows, though it introduces complex technical and computational demands.
At its core, the underlying architecture relies on deep synchronization between speech synthesis, reasoning engines, and graphic generation. When integrated into Gemini 3.8 Live, the video rendering component must operate under strict latency limits to prevent noticeable conversational delays that destroy user engagement. The system utilizes low-latency video generation algorithms that dynamically align oral movements, micro-expressions, and head posture with generated speech output in real time. In real-time speech interactions, Gemini 3.5 Transcribe speech capabilities demonstrate how low-latency processing operates under strict bounds.
To maintain natural interaction, the platform focuses heavily on fluid turn-taking and continuous contextual comprehension. Traditional conversational IVRs and early conversational agents often suffered from awkward pauses or rigid mechanics that broke user immersion. By utilizing the advanced reasoning capabilities inherent in Gemini 3.8 Live foundation models, these digital personas can process incoming user audio while simultaneously generating contextual responses and executing background tasks. This allows an avatar to engage in natural dialogue without freezing or requiring the user to wait while the system queries corporate databases.
How Gemini 3.8 Live Integrates Real-Time Visual Personas
The functional integration of Live Avatar with the broader Gemini ecosystem enables advanced tool execution during active dialogue. In typical enterprise support scenarios, an automated agent must retrieve account details, execute transaction checks, or query enterprise resource planning systems while maintaining a natural conversation. Gemini’s advanced reasoning engine allows the Live Avatar system to initiate background tool calls and perform asynchronous data fetching without interrupting visual or auditory delivery. As a result, the digital agent can verbally address a customer while simultaneously pulling real-time flight changes, billing histories, or order statuses into the active session.
This real-time tool calling capability represents a major departure from previous generations of synthetic video avatars. Earlier market offerings were largely limited to pre-rendered video clips stitched together sequentially or static avatars that paused complete audio delivery while awaiting API responses. By unifying the reasoning layer with live video streaming pipelines, Google enables a much more cohesive user experience. However, maintaining low latency across global enterprise deployments requires robust server infrastructure and carefully managed edge network routing.
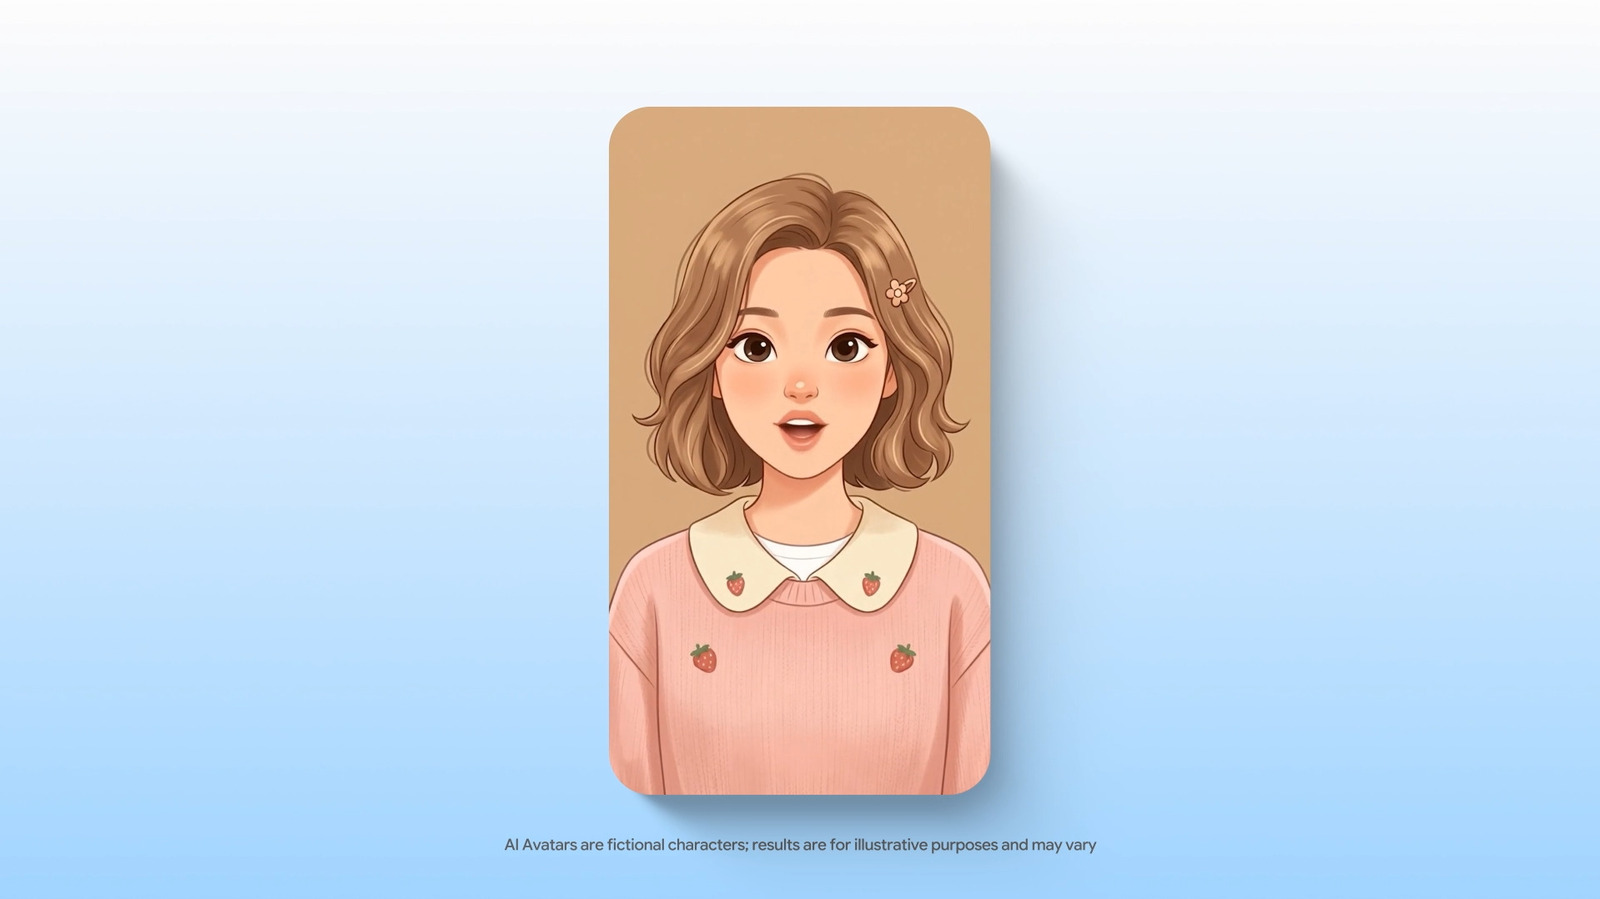
The visual fidelity of the avatars spans a range of designs, extending from realistic human depictions to stylized character models. This spectrum allows enterprise clients to select a visual persona that matches their specific brand strategy or customer service vertical. For instance, financial institutions might opt for conservative human appearances to instill trust during account queries, whereas interactive gaming platforms or lifestyle brands might deploy animated figures. Regardless of visual style, the platform emphasizes micro-expressions and contextual visual cues, ensuring that the avatar’s emotional delivery matches the tone of the underlying text generation.
Enterprise Customization and Security Safeguards
To accommodate corporate branding requirements, Google provides a library of pre-designed stock avatars while offering custom avatar generation options for select organizations. Through custom avatar pipelines, businesses can input high-quality reference images to construct bespoke visual personas that align precisely with corporate mascots or brand aesthetics. However, access to this customization toolchain is strictly restricted to allowlisted enterprise clients operating within the Gemini Enterprise framework. Google enforces this allowlist model to mitigate potential unauthorized identity replication and safeguard high-profile visual assets from misuse.
The proliferation of high-fidelity synthetic personas brings significant security risks, particularly regarding identity spoofing and deepfake proliferation. To address these threats, all visual content output generated through Gemini 3.8 Live with Live Avatar is embedded with SynthID watermarking technology. Developed by Google, SynthID inserts imperceptible digital watermarks directly into the generated video frames and audio tracks without degrading visual quality. According to details published on Google’s official release page, these safeguards ensure synthetic agents remain transparent while preventing unauthorized manipulation. Potential security vulnerabilities and autonomous tool failures are addressed in our analysis of AI model misalignment risks.
Despite the technical sophistication demonstrated by live visual agents, enterprise IT leaders face substantial operational tradeoffs when considering implementation. Chief among these constraints is the immense computational overhead associated with real-time generative video rendering. Unlike traditional text or voice-only chatbots, streaming high-definition video synthesized on a frame-by-frame basis demands significant graphical processing unit capacity and bandwidth allocation. For enterprises handling millions of inbound customer support calls daily, the infrastructure costs associated with live video generation could easily outweigh the efficiency gains realized from automated labor reduction.
The evolution of real-time conversational AI from basic voice synthesis to dynamic video avatars marks a structural shift toward fully multimodal interaction models in enterprise infrastructure. As cloud computing costs adjust and generative visual models become increasingly efficient, visual AI agents will likely define the next baseline for corporate digital touchpoints. The ultimate adoption curve, however, will depend heavily on how effectively organizations balance computational rendering expenses, user experience preferences, and strict cryptographic safeguards against synthetic identity misuse.